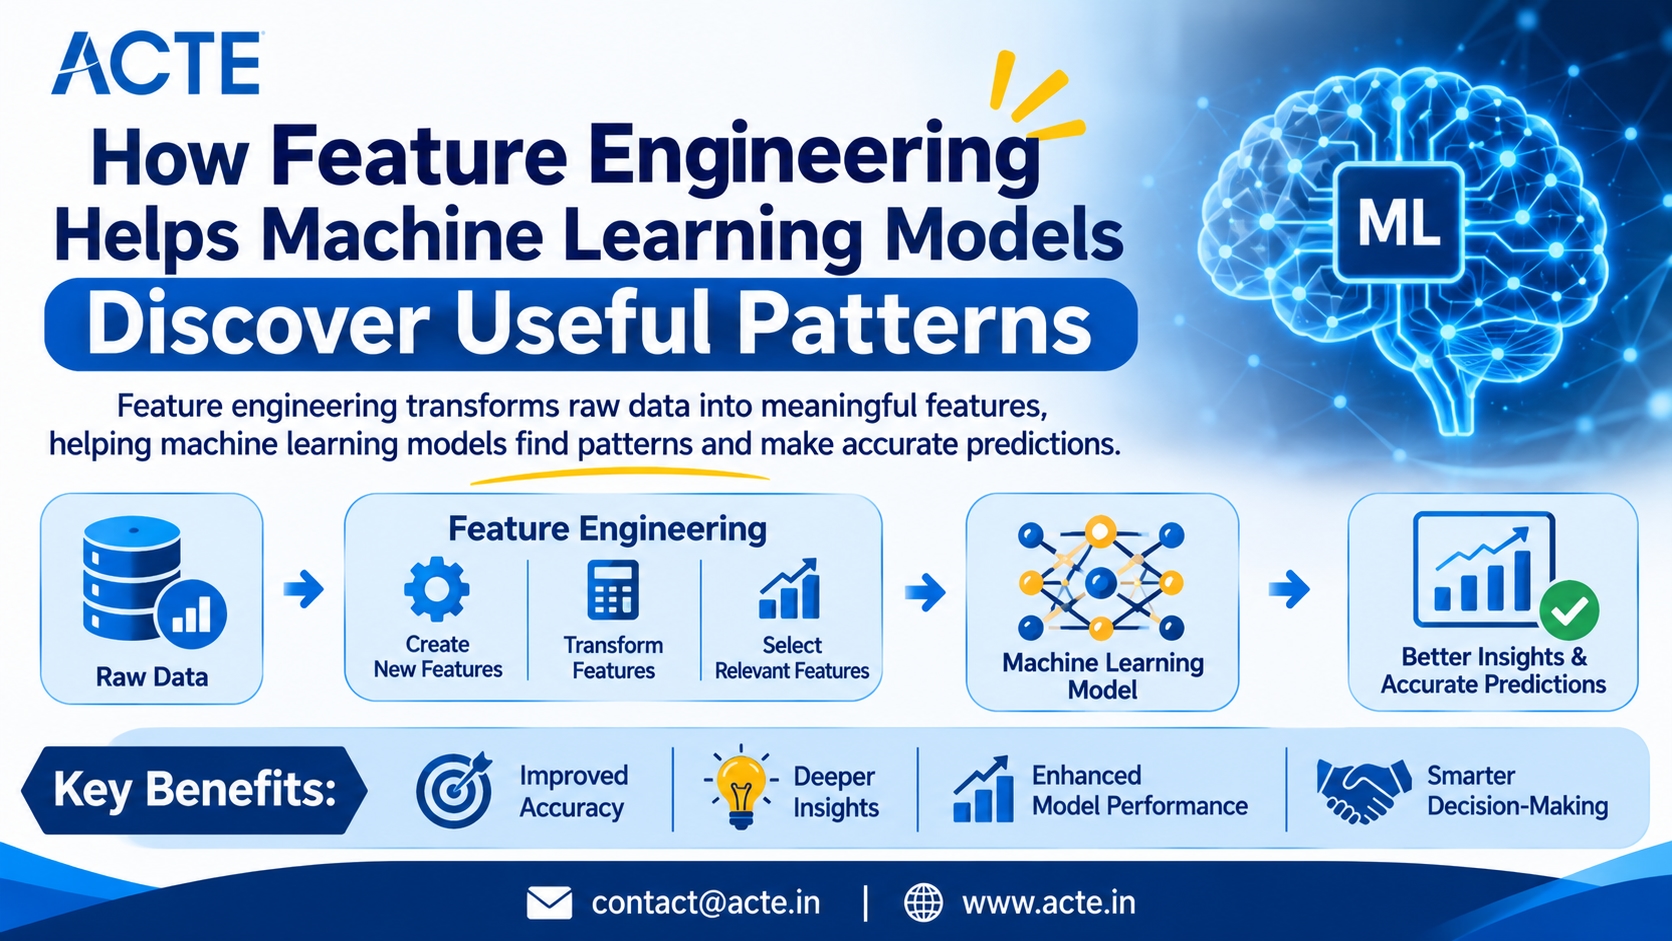
Feature engineering plays a major role in developing effective machine learning models by helping algorithms extract useful information from raw datasets. Unprocessed data may contain irrelevant values, missing information, and inconsistent formats that make pattern recognition difficult. By transforming existing attributes and creating meaningful features, data professionals can improve model accuracy and generate more dependable predictions. Understanding these techniques is essential for building practical machine learning solutions.
Exploring How Feature Engineering Supports Machine Learning
Feature engineering is the process of selecting, transforming, and developing data attributes that improve the learning process. Machine learning algorithms depend on the quality of input features to identify relationships and make predictions. Relevant features help models recognize important information while reducing unnecessary complexity. Professionals enrolling in Data Science and AI Training in Chennai can strengthen their understanding of these methods through practical exercises and project-based learning.
Converting Raw Datasets into Structured Information
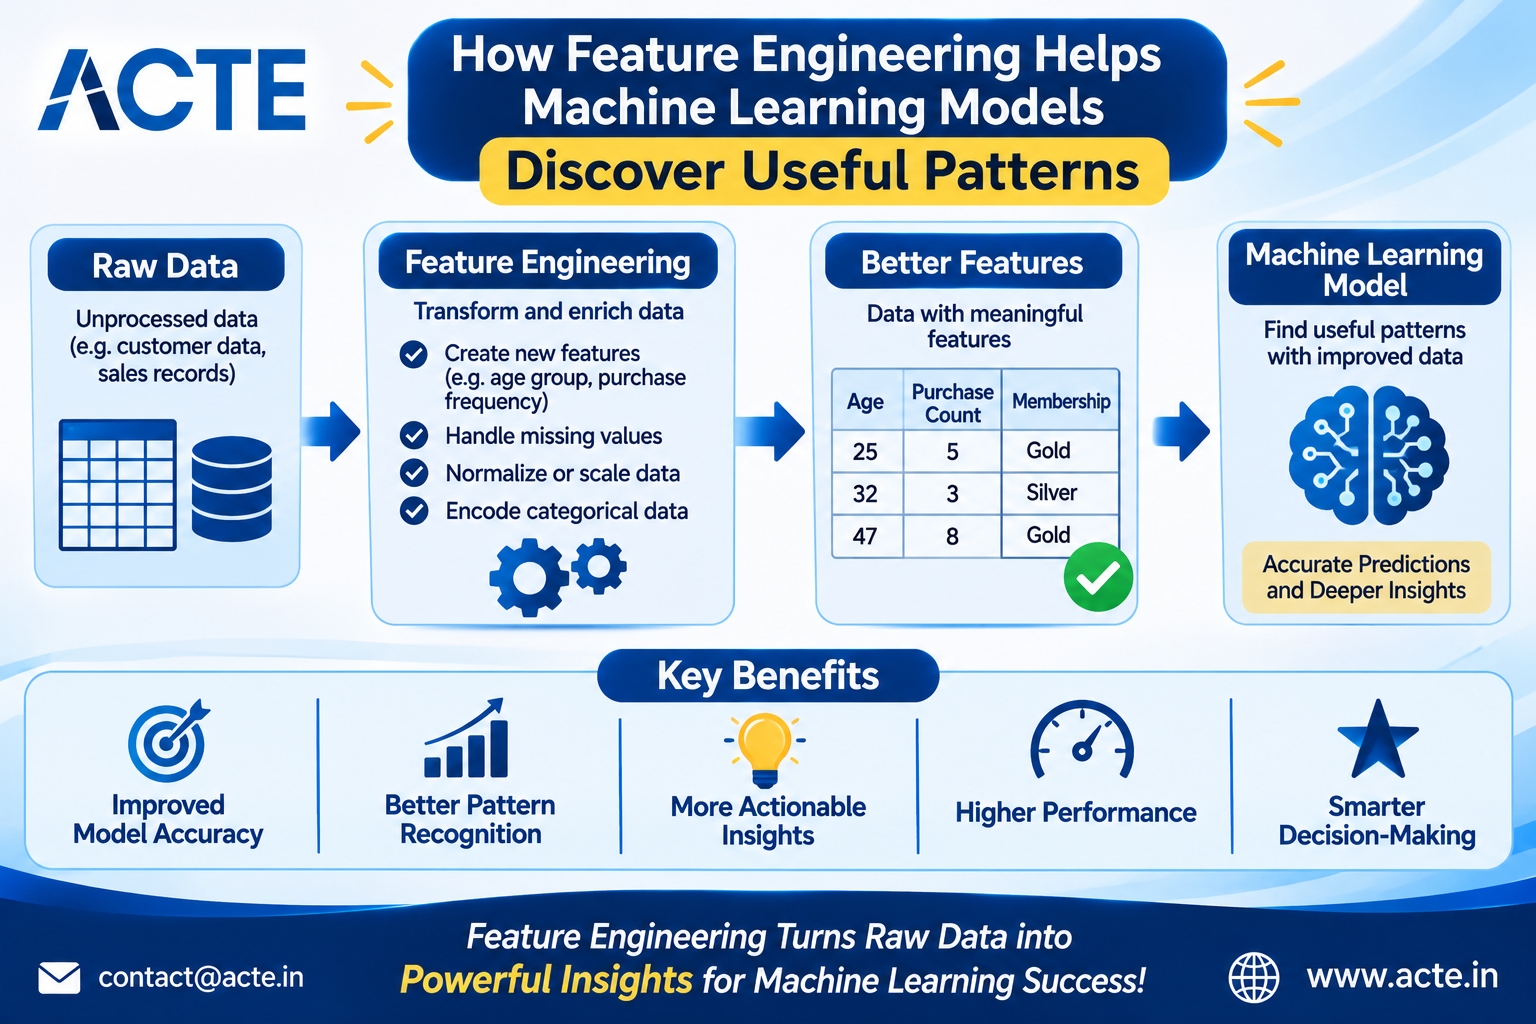
Raw data often includes incomplete records, duplicate entries, inconsistent values, and unnecessary columns. Before training a model, these issues must be addressed through appropriate preprocessing techniques. Data cleaning, missing-value treatment, categorical encoding, and numerical scaling help create organized datasets. Removing irrelevant information also allows algorithms to focus on attributes that contribute to meaningful predictions. A well-prepared dataset provides a stronger foundation for machine learning development.
Developing Useful Features to Reveal Hidden Relationships
Creating new features allows data scientists to extract additional meaning from existing attributes. For example, timestamps can be transformed into information about weekdays, months, or seasonal trends. Customer transaction records can generate features such as average order value, purchase frequency, and spending patterns. These transformations provide additional context that helps algorithms recognize relationships within complex datasets. A Data Science and AI Course in Bangalore can help learners explore these techniques through practical machine learning activities.
Identifying Important Variables Through Feature Selection
A dataset may contain many attributes, but not all of them contribute equally to model performance. Including unnecessary variables can increase processing time and introduce noise into the learning process. Feature selection techniques help identify the most valuable attributes using statistical tests, correlation analysis, and feature importance methods. Choosing relevant features can improve model efficiency, simplify interpretation, and reduce overfitting.
Understanding Industry Applications of Feature Engineering
Feature engineering is widely used in industries that depend on data-driven decisions. Healthcare organizations analyze patient records to identify risk factors and support early diagnosis. Banks examine transaction characteristics to recognize suspicious financial activity. Retail companies use customer purchase history to improve recommendations and forecast product demand. Manufacturing businesses also create features from equipment sensor data to identify maintenance requirements and potential failures.
Exploring Python Tools for Feature Engineering
Python offers several libraries that make feature engineering more efficient. Pandas supports dataset manipulation, filtering, and transformation, while NumPy helps perform numerical calculations. Scikit-learn provides tools for data preprocessing, feature extraction, encoding, and selection. Visualization libraries such as Matplotlib and Seaborn help identify distributions, correlations, and unusual patterns. A Data Science and AI Course in Hyderabad can provide opportunities to apply these tools while working with different datasets.
Strengthening Technical Knowledge Through Machine Learning Projects
Practical projects allow learners to understand how feature engineering affects predictive performance. Activities involving customer segmentation, fraud detection, sales prediction, and loan eligibility analysis provide experience in preparing datasets and developing relevant attributes. Evaluating model results before and after feature transformations also helps learners understand the importance of feature quality. Enrolling in a Data Science and AI Course can support skill development through hands-on assignments and industry-oriented projects.
Conclusion:
Feature engineering enables machine learning algorithms to identify valuable patterns by converting raw data into meaningful information. Techniques such as data preprocessing, feature creation, and feature selection help improve prediction quality and computational efficiency. Developing practical knowledge of these methods allows aspiring data professionals to create more effective models and solve real-world problems. Consistent practice with Python tools and machine learning projects can build a strong foundation for a career in data science and artificial intelligence.